Your AI workflow executes with 0 errors and the webhook returns 200 OK. So why is the client still complaining about lost productivity?
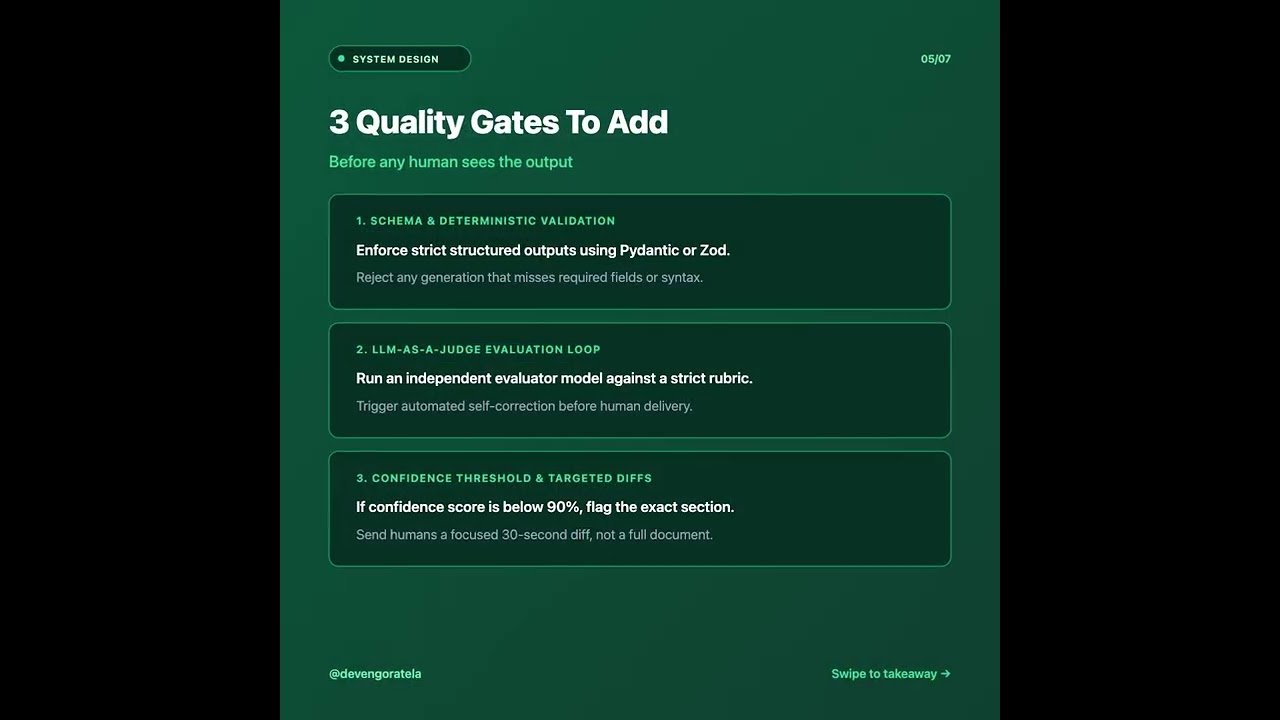
In this video, we break down a massive finding from G2’s 2026 AI Agents report: 45% of B2B teams report that fixing agent mistakes eats over 25% of their expected time savings. We explore the critical shift from measuring “cost per run” to “cost per usable result” and walk through 3 production quality gates you can implement to stop broken deliverables from reaching human hands.
WHAT YOU WILL LEARN:
• Why 100% execution uptime can disguise negative automation ROI
• The True Cost Formula: factoring API tokens, retry compute, and human review time
• How to implement deterministic schema validation using Pydantic or Zod
• How to build an LLM-as-a-judge evaluation loop with automated self-correction
• How to implement confidence scoring so humans only review targeted diffs
TIMESTAMPS:
00:00 – The Green Checkmark Illusion
01:25 – The Shocking 45% Stat from G2’s Report
03:10 – Vanity Metrics vs. What Clients Actually Experience
05:15 – The True Cost Formula: Cost Per Usable Result
07:40 – Quality Gate 1: Deterministic Schema Validation
10:05 – Quality Gate 2: LLM-as-a-Judge Eval Loops
12:30 – Quality Gate 3: Confidence Scoring & Targeted Diffs
14:50 – The Mindset Shift Every AI Builder Needs
16:15 – Final Thoughts & Action Steps
RESOURCES & LINKS:
• Practical AI Community: https://skool.com/practical-ai
• Connect on LinkedIn: https://www.linkedin.com/in/devengoratela/
• Code examples & templates: https://github.com/devengoratela
ABOUT DEVEN GORATELA:
Sharing practical AI workflows, automation architectures, and agentic engineering patterns that save real hours.
Subscribe for new AI tutorials and automation blueprints every week.
#AIagents #AIautomation #AIworkflowautomation #LLMevaluation #costperusableresult
Video Source
About the Author